Local self-hosted
$0
one-time
The official code and model weights are released under the MIT License. Users provide their own compute, storage and deployment infrastructure.
Check current pricing →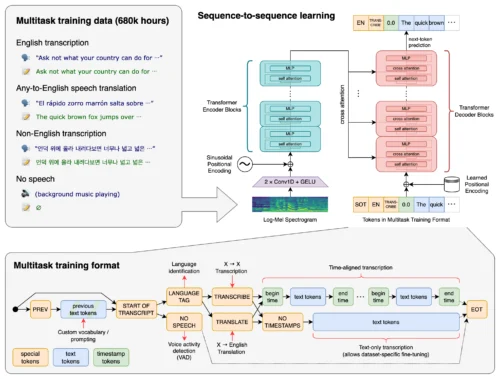
OpenAI Whisper is an open-source multilingual speech recognition model for transcription, speech translation, language identification and timestamped audio processing.
A quick way to understand who this product may suit, where its limits matter, and which facts are most relevant before you compare alternatives.
API, Command line, Linux, macOS, Python, PyTorch
8.1/10
OpenAI Whisper is an open-source automatic speech recognition model released in September 2022. It converts audio into text, identifies spoken languages, and translates supported non-English speech into English.
The official implementation uses a Transformer encoder-decoder architecture. It processes audio in 30-second windows and supports local inference through Python code or a command-line interface.
Whisper is available in multiple model sizes, including tiny, base, small, medium, large and turbo. Larger models generally require more memory and provide different speed and accuracy trade-offs.
The official code and model weights are released under the MIT License. Users provide their own compute, storage and deployment infrastructure.
Check current pricing →OpenAI's hosted whisper-1 model supports audio transcription and translation through API endpoints.
Check current pricing →Pricing may change. Verify current plans on the vendor's website.
Compare similar products directly, then see which alternatives may make more sense when your requirements differ.
These products address broadly similar requirements. The descriptions focus on documented reasons a buyer might compare them with OpenAI Whisper.
| Product type | Open-source automatic speech recognition model |
|---|---|
| Developer | OpenAI |
| Original release | September 2022 |
| License | MIT |
| Local runtime | Python and PyTorch |
| Supported local operating systems | Linux, macOS and Windows |
| Command-line interface | Yes |
| API model | whisper-1 |
| API endpoints | /v1/audio/transcriptions and /v1/audio/translations |
| API pricing | $0.006 per minute |
| API upload limit | 25 MB for whisper-1 transcription uploads |
| API supported formats | mp3, mp4, mpeg, mpga, m4a, wav and webm |
| Integrations | Python, PyTorch, FFmpeg, OpenAI API and OpenAI SDKs |
| Free trial | No separate Whisper trial verified |
| Realtime streaming | Not supported by whisper-1 API |
| Languages | 98 languages listed in OpenAI documentation |
| Model sizes | tiny, base, small, medium, large and turbo |
A proprietary editorial score based on product capabilities, usability, value, performance, support and user sentiment evidence.
Whisper provides multilingual transcription, translation, language detection, timestamps and several model sizes. The MIT license supports self-hosting, but installation requires Python, PyTorch, FFmpeg and suitable hardware. OpenAI documentation now recommends newer transcription models for some general-purpose API workloads.
Methodology v1.0. The assessment weighs feature coverage (25%), ease of use (15%), value for money (20%), performance (15%), support (10%) and user sentiment (15%), using researched product evidence and verified review evidence where available. It is a TechZella editorial assessment, not a direct user-review average.
No reviews yet. Be the first to share your experience.
Please log in to submit a review.
The local implementation is available under the MIT License and has no software charge. Hosting, compute and storage costs still apply. The hosted Whisper API is billed at $0.006 per minute.
Yes. The official repository supports downloading model files and running inference locally without sending audio to OpenAI’s API.
The documented installation process covers Linux, macOS and Windows. It runs through Python and PyTorch rather than a standalone native desktop application.
Yes. Multilingual models can translate supported non-English speech into English. The turbo model is intended for transcription and isn’t trained for translation.
The official Whisper implementation provides transcription, language detection, translation and timestamps. Speaker diarization isn’t listed as a built-in feature in the official repository.
The local model can be incorporated into streaming applications, but the hosted whisper-1 API doesn’t support streaming. Realtime workloads require an application-level implementation or another OpenAI transcription model.